Artificial Intelligence
Transformers and large language models - how they work at a high level
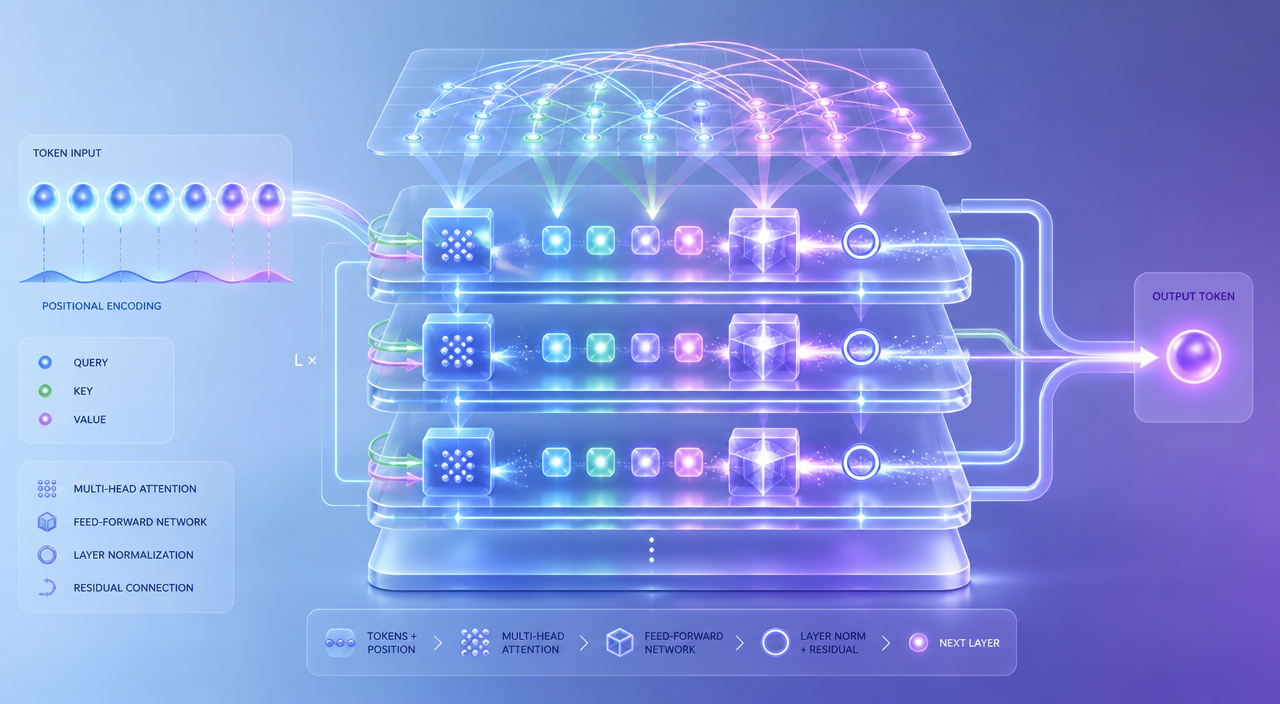
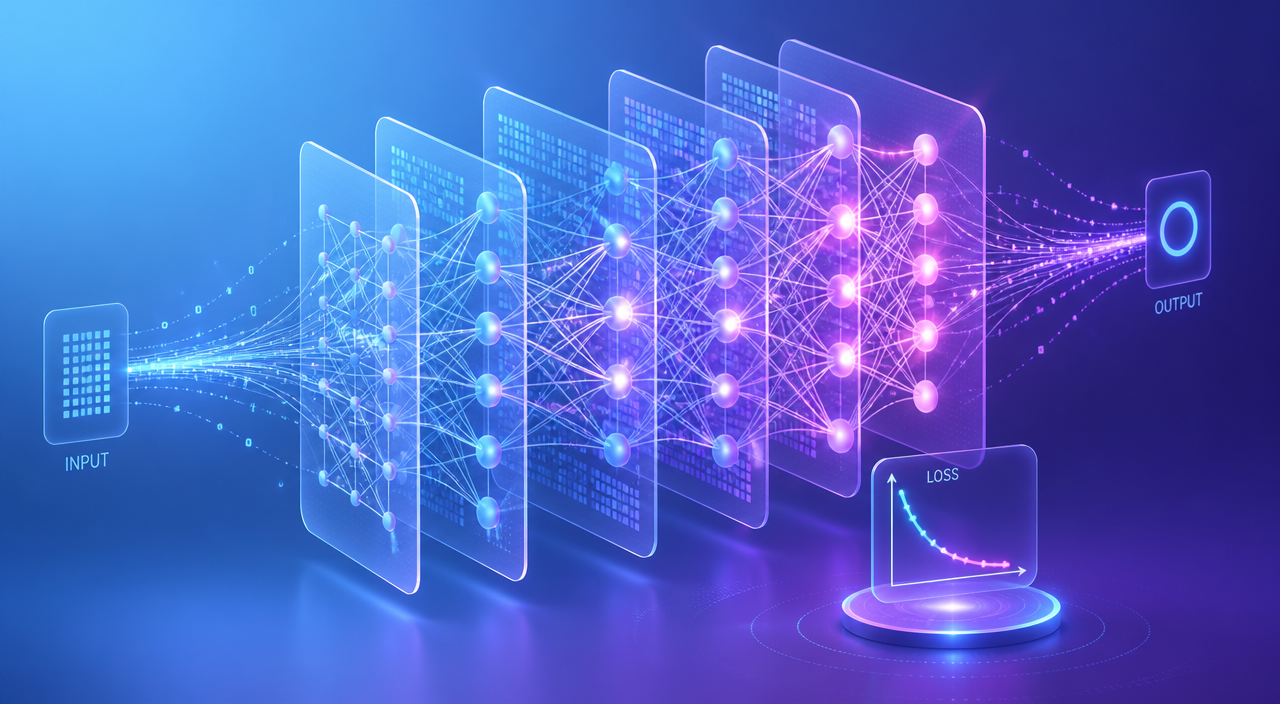
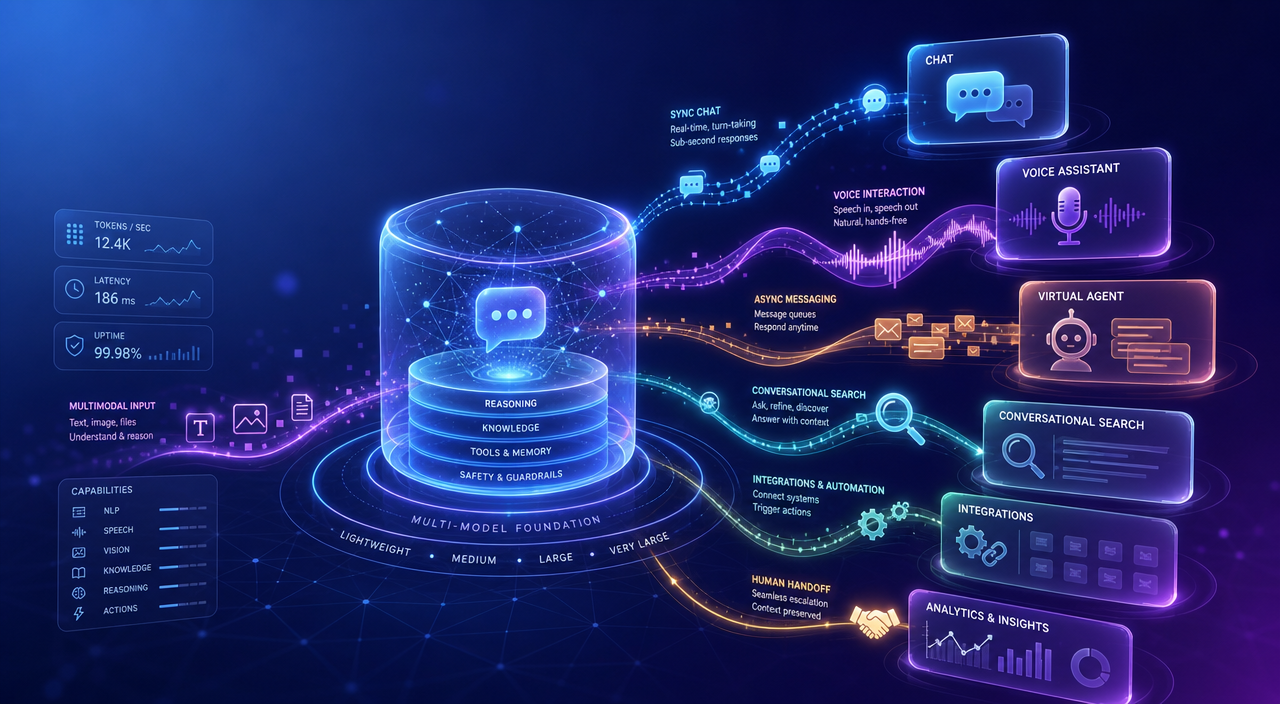
Modern systems that generate or understand natural language are built on the same underlying idea: a network that learns relationships across words or tokens and can use those relationships to predict, rank, or produce text. For someone deciding how these systems behave, it helps to separate three things: the basic architecture that makes the behavior possible, the way models are trained before any task-specific use, and the runtime mechanics that turn internal representations into visible text. The following explains those layers at a practical, non-technical level and highlights the tradeoffs you'll encounter when using large language models.
AR
Alex Rivers